
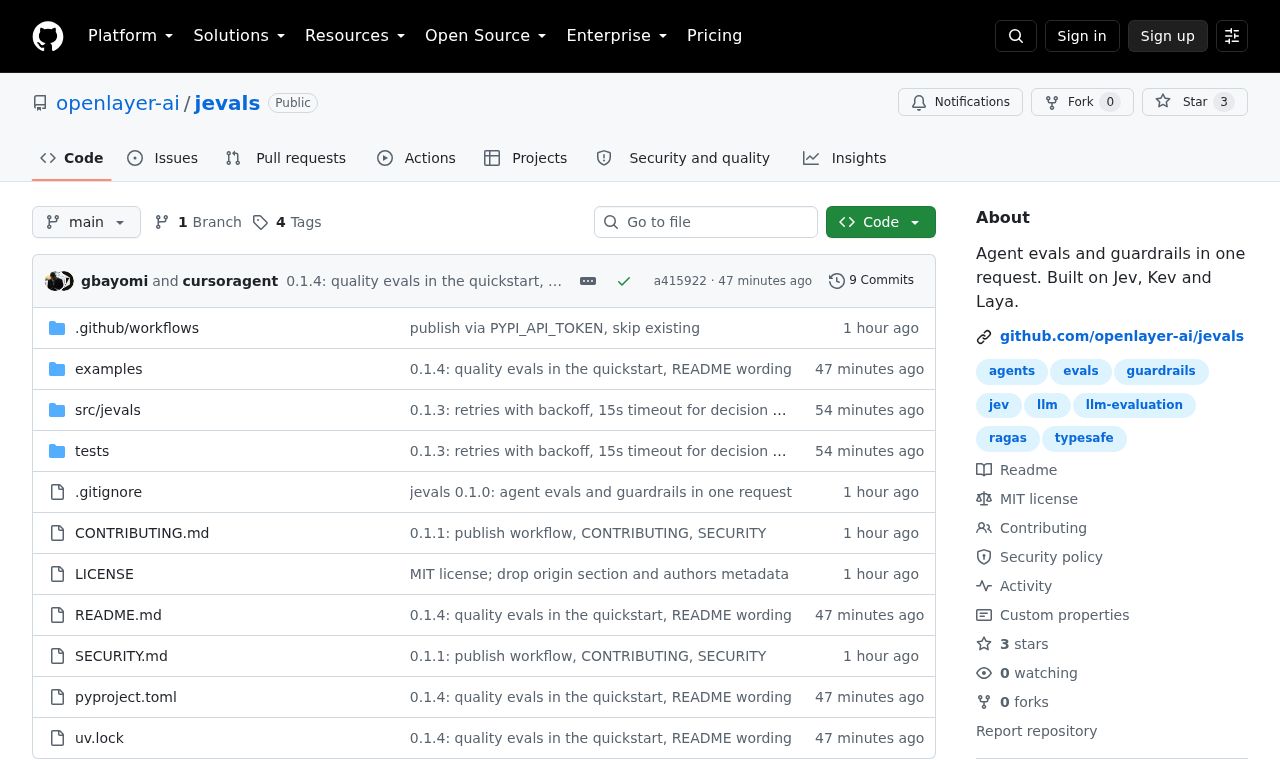
 SITE CAPTURE
Based on information published on the service's website. Selection and review policy
WHAT IT DOES
What does it do?
jevals uses Jev-style decision models instead of LLM judges to run agent evaluations and guardrails. It combines the state and questions of multiple evaluations into one request per trace, and the same definitions can be reused for offline metrics, production monitoring, and gates inside agents. It supports synchronous and asynchronous execution, with Jev API, local Kev or Laya on Mac, and general chat LLMs as backends.
KEY FEATURES
Key features
- Process all evaluations for a trace in a single request
- Support yes-or-no, multiple-choice, and rubric-scored questions
- Reuse the same definitions for offline metrics, production monitors, and agent gates
- Support synchronous evaluate and asynchronous aevaluate
- Support Jev, local Kev and Laya, and general chat LLM backends
- Combine code-based checks with typed judgment questions