danwo
Adds replayable natural-language steps and backend failure checks to web and mobile UI tests.
Developer toolsOpen source
Loading page
Adds replayable natural-language steps and backend failure checks to web and mobile UI tests.
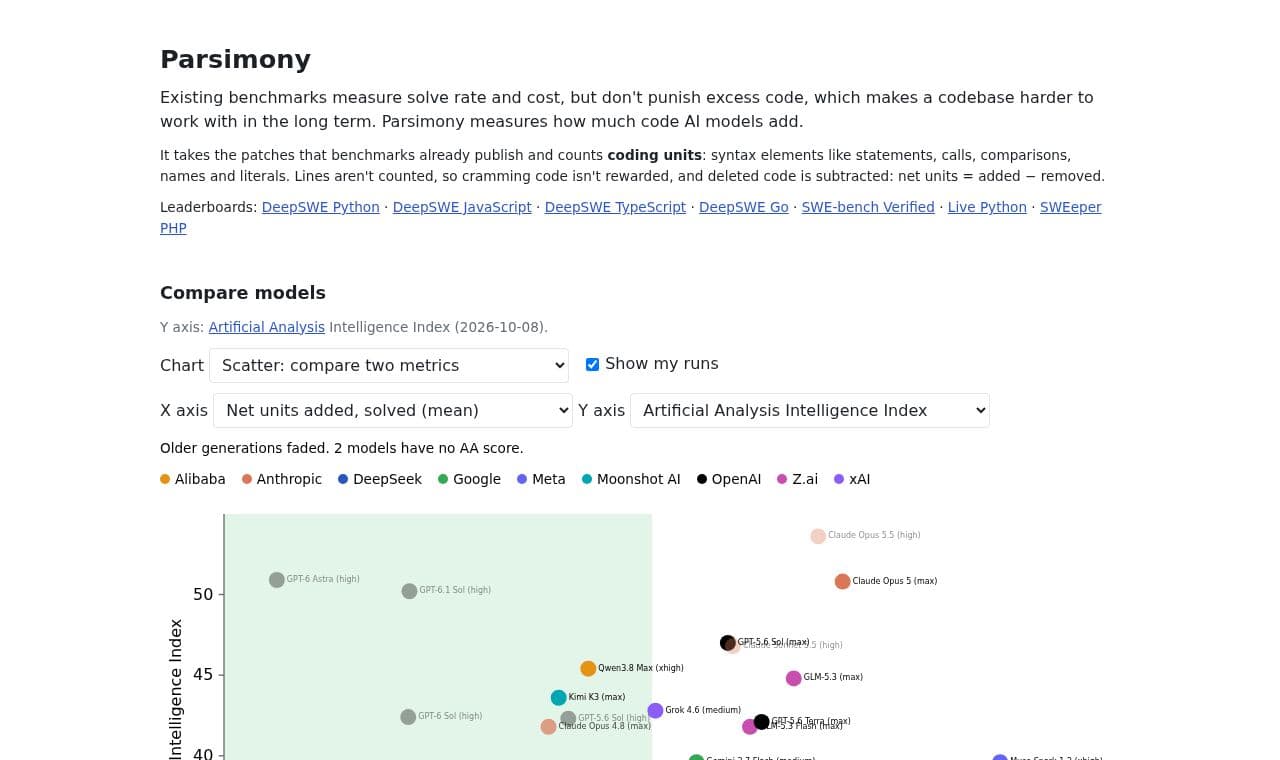
An open-source benchmark that compares how much code AI coding models add, measured in syntactic units.
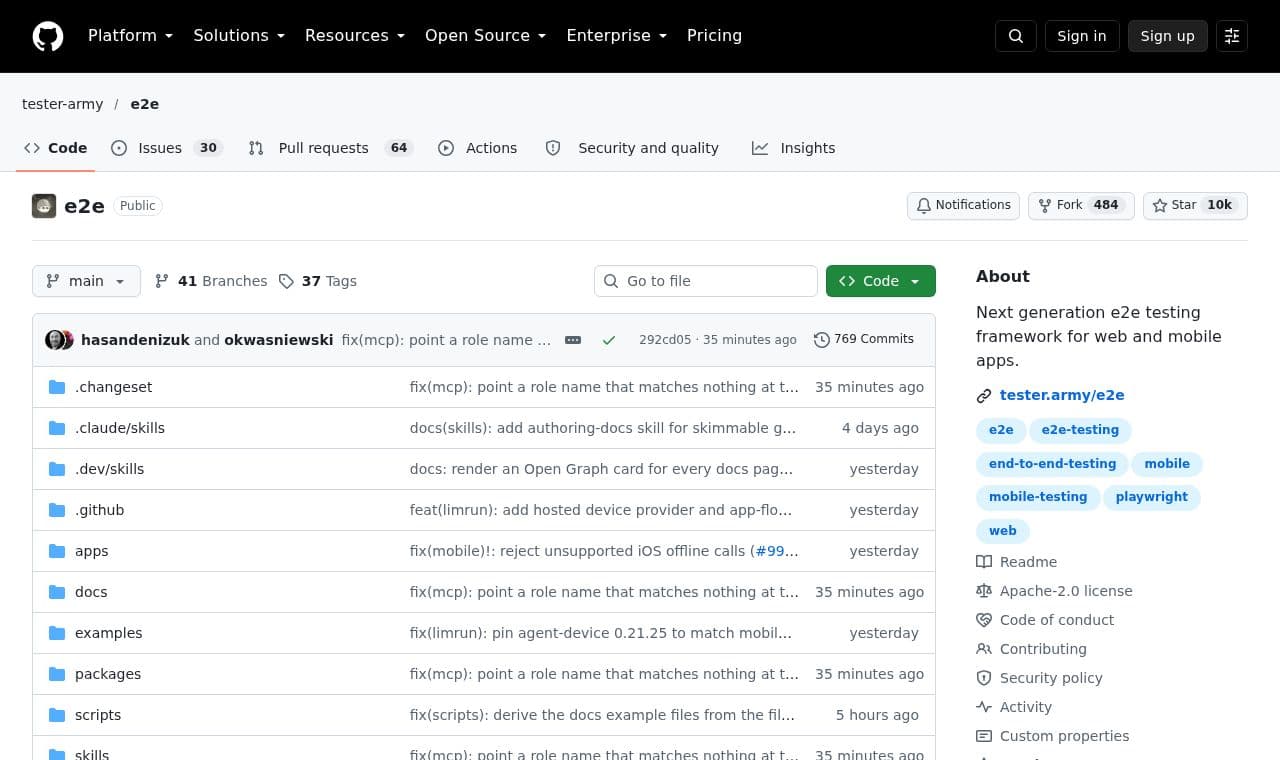
A testing framework that operates apps from natural-language goals and reuses verified actions in later runs.
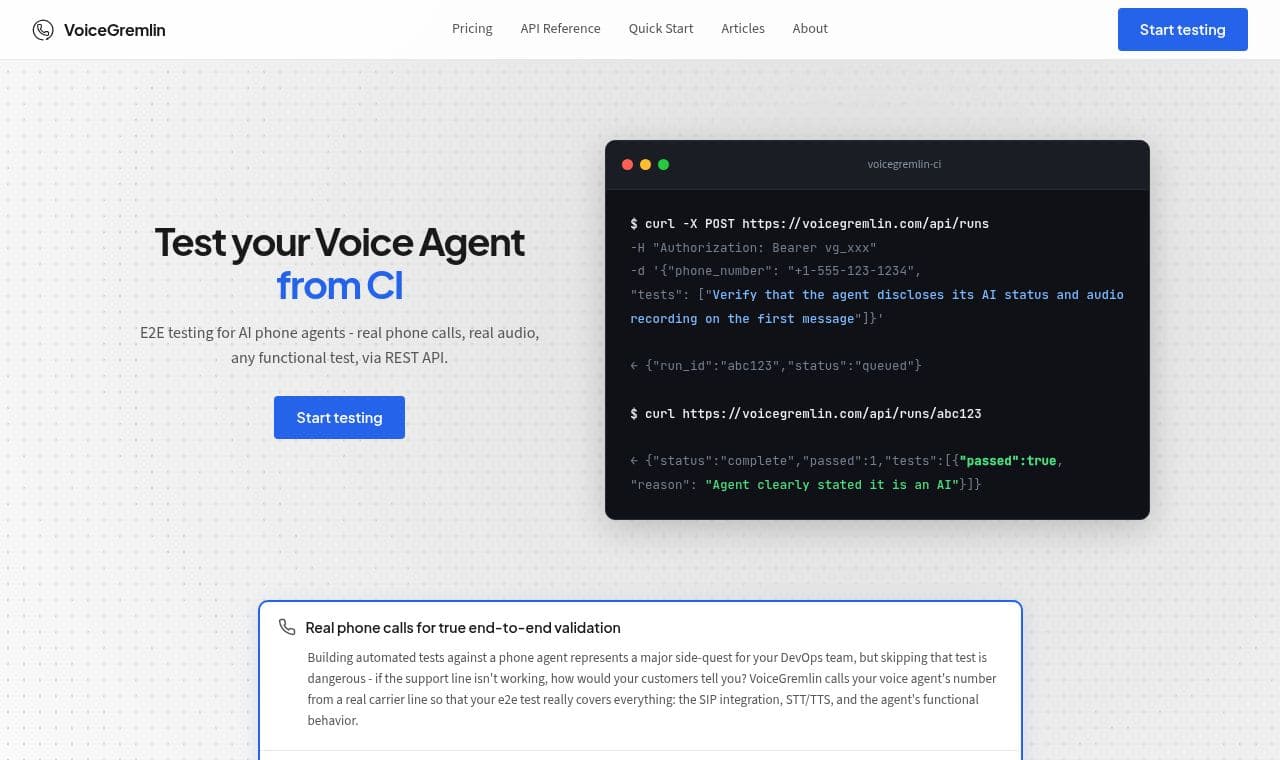
A tool that tests AI voice agents through real phone calls and returns pass or fail results to CI.
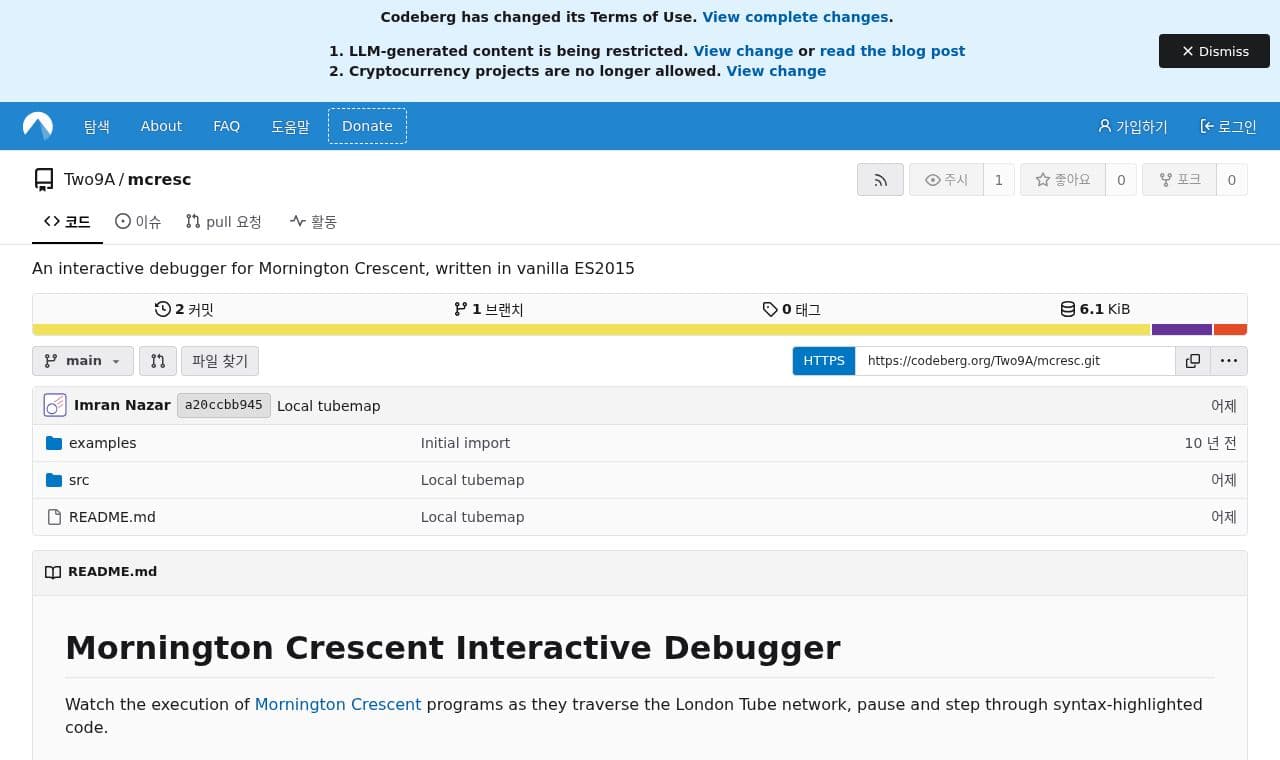
A debugger that uses a London Underground map to explore the execution of an esoteric language.
A public benchmark that compares agent memory systems using the same procedure
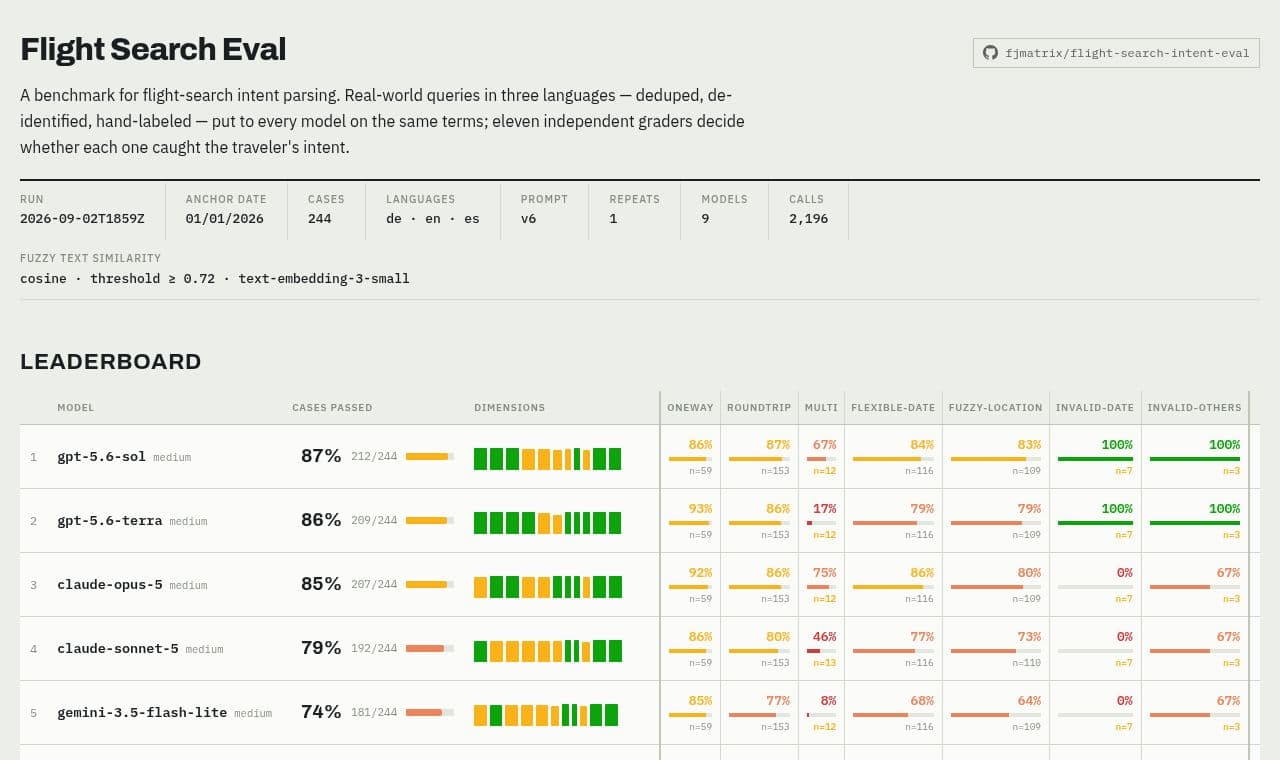
A benchmark for evaluating flight search intent parsing with real queries in three languages